I watch my AI usage more closely than I expected to.
I want enough allowance available when I need it. But I also hate getting to the weekly reset with capacity left unused. I have paid for it. Surely I should be getting something out of it?
Apparently, a home lab, infrastructure dashboards and the occasional electricity bill were not enough. I now have another meter to watch.
The infrastructure guy in me recognises this conversation. We have spent years looking at cloud consumption, unused capacity and whether the bill reflects something useful. Now I am asking similar questions about AI. How do I make what I am already paying for go further, without making the work slower, harder or worse?
That is the part of tokenomics that interests me. I want to understand what the consumption buys me. Can I get more useful work done within the same budget? Can I improve the quality? Can I spend less time explaining the job again or fixing what comes back?
Mike Fuller makes a useful distinction in a FinOps Foundation article about how FinOps and tokenomics fit together. Understanding the spend and making the engineering choices that improve it are connected pieces of work.
That resonates with what I am trying to work through here. Watching my weekly allowance tells me something about consumption. Choosing an appropriate model, avoiding repeated explanation and deciding where code can help are decisions that might improve what I get from it. I need to connect those decisions with the quality of the work that comes back.
I don't need a finance department in the home lab to start asking those questions.
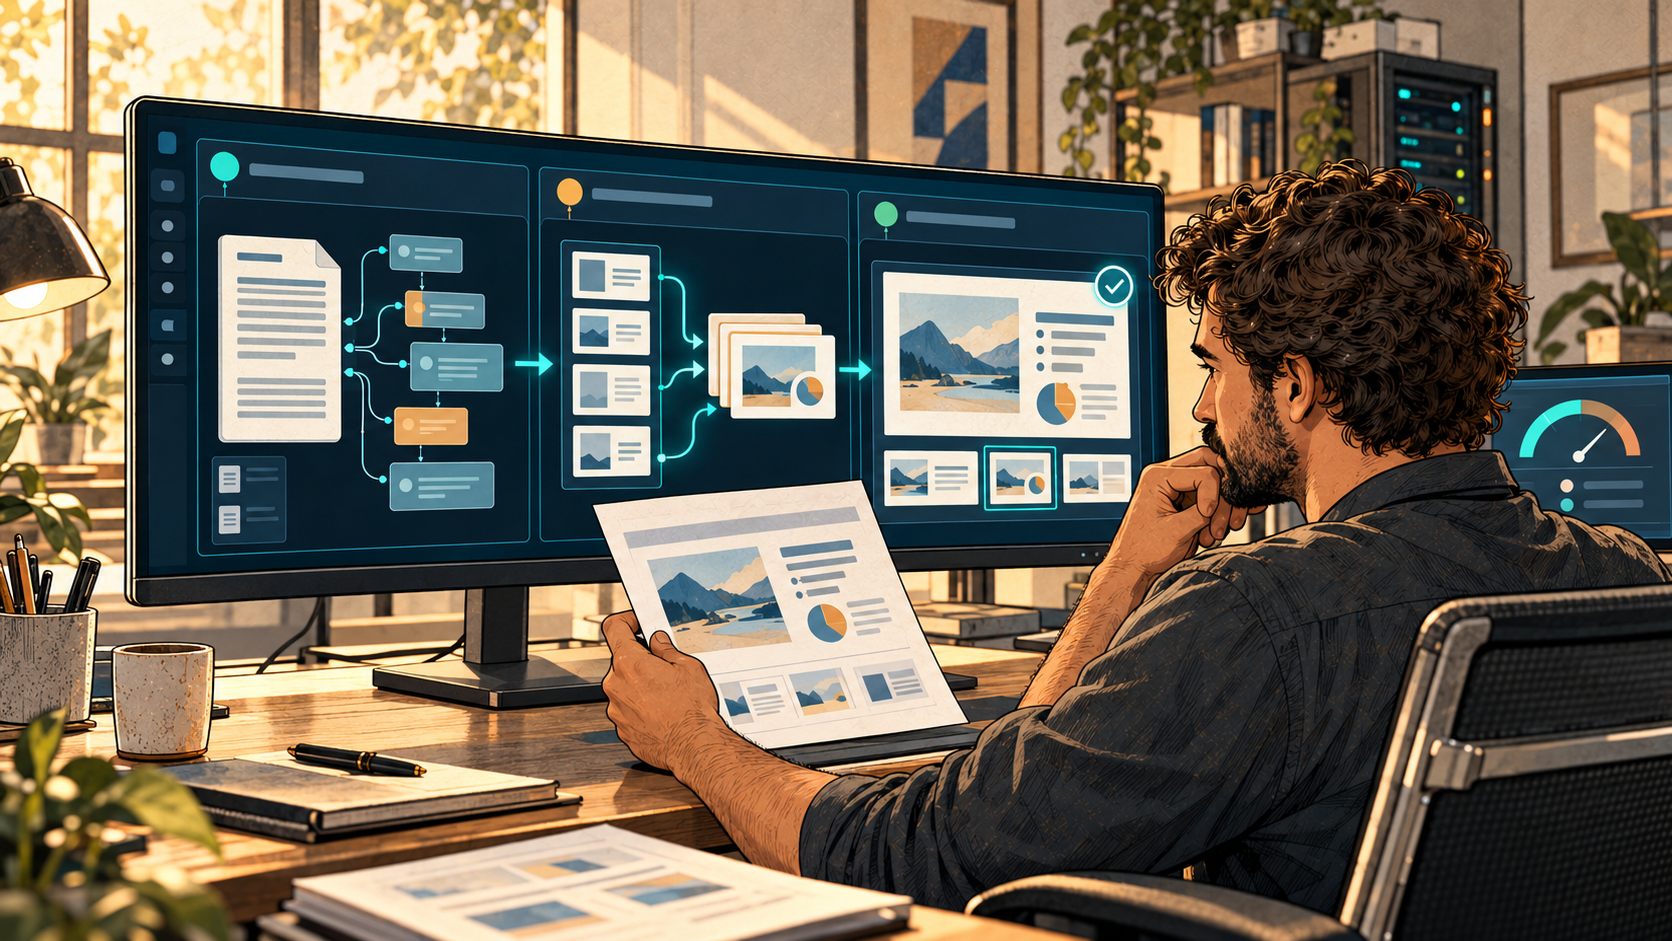
Read the image description
The usage indicator is one signal. The main work journey combines thinking, repeatable assembly and human review to reach a useful output. The scene is conceptual and contains no measured token or cost comparison.
What am I actually paying for?
My weekly-reset concern is about usage included in subscriptions. It is different from paying for model calls through an API. The distinction changes what an improvement looks like.
If a subscription costs the same each month, reducing consumption does not automatically reduce the bill. The benefit might be more useful work within the allowance, fewer interruptions or capacity available when a difficult job turns up. If I am paying by usage, reducing unnecessary calls may affect the direct cost as well.
Local models bring another arrangement. There may be less reliance on a remote provider for selected work, but hardware, power and the time to maintain it still belong somewhere in the calculation. Moving the work does not make its cost disappear.
I also need to be careful about the meter itself. A provider's subscription allowance is not necessarily a simple pot of raw tokens. I can't assume that reducing a recorded token count by a certain amount gives me the same percentage back on a subscription usage display.
So I want to keep three things in view: the money I pay, the capacity available to me and the effort required to get a useful result. Watching only one gives me a fairly incomplete picture.
Where does the week go?
Some work deserves a long conversation. Developing an idea, challenging an architecture or finding the hole in a response can take several passes. If another round changes a decision or catches a serious mistake, I am quite happy to have spent the allowance on it.
What I want to understand is the rest of the journey. How much goes into getting the model back to the point we had already reached? How often are we rebuilding a familiar output, passing the same material between agents or correcting something that a clearer brief could have prevented?
An unclear instruction can become a surprisingly expensive conversation. Each correction adds another opportunity to misunderstand the requirement. A chain of agents can add useful independent challenge, but it can also mean several models reading and explaining the same material before anyone produces the thing I wanted.
Those are places I would look before assuming I need another subscription or a larger allowance. The question is whether the extra activity helped the job. A long investigation can be valuable. A long loop around a settled instruction is worth questioning.
Making the capacity go further
The first choice is how much capability the task needs. A difficult design decision may justify a capable model and a substantial amount of context. A bounded transformation may be handled by a less expensive model or by code. I want to make that choice against the quality required, rather than send every task to the most capable option simply because it is available.
The cheapest attempt can become expensive if it needs several repairs. Equally, a powerful model is doing a fairly mundane job if all I need is a defined set of fields checked against a rule. The sensible choice depends on the work and what I can trust the result to do.
The next opportunity is to preserve what we have already worked out. A useful brief, clear output requirements and a concise record of decisions give the next interaction a better starting point. There is still effort in reading that context, but less reason to spend a conversation reconstructing the whole story or sending an entire history when a focused handoff would do.
Then there is repeatable execution. In the frameworks I have been working on for reviewing and responding to RFIs and RFPs, presentation generation is a useful example. AI can help interpret the requirement, challenge the response and develop the narrative. Once the content structure is clear, a Python renderer can handle the defined assembly into PowerPoint.
That is one way to direct model effort towards the parts that need judgement. Python, Terraform and Ansible have different jobs, but they all offer ways to encode repeatable methods. The inputs can change while the method remains useful. We do not need every run to become a new exercise in working out how to do the job.
There is an investment involved, though. Someone has to build, test and maintain that automation. If the task happens once, or the desired output keeps changing, I may be better off working through it with a model and a person. I don't want to save a little usage by creating a permanent collection of scripts that need looking after.
Nor does putting a job in a script make it token-free. A script may call models, retry failures or ask another model to assess the result. The surrounding agents can consume plenty of context deciding what to run and interpreting what came back. I need to follow the complete job to see where the improvement might be.
Quality changes the arithmetic
Bob, my AI personal assistant and partner in crime, found a useful example when he looked back through our earlier work.
His notes describe a set of dashboards produced by a shared generator. The query checks passed. The recorded feedback from me was that the main overview was hard to read. The code had done its assembly work, but the result still needed a better visual design.
Changing the generator meant the correction could flow through the set. Before that, it had been repeating the same weak design. As Bob put it: “Automation is a multiplier. It multiplies consistency, but it can also multiply the wrong choice.”
An older VNI presentation he flagged makes a related point. It is a PowerPoint file whose slides are full-page images. The words and diagrams are baked into the pictures. That deck is separate from the current Python rendering work, but it shows why “editable presentation” needs a clearer definition than producing a file with the right extension.
Both examples bring me back to the economics. If I have to spend more time making the output usable, that effort belongs in the assessment. A fast generation and a green check can still leave me with a job to finish.
There are also checks I would deliberately keep spending model effort on. Repeating behavioural tests after an agent changes can reveal a problem that structural checks will miss. Reviewing an important claim or challenging a questionable recommendation may consume more allowance and still be the best use of it that day.
An optimisation that removes useful review can create much more expensive problems later. Quality, security and the right person approving consequential actions are part of the work we need to support.
What would a better week look like?
In the frameworks I have been building for managed and professional services responses, we have a step I call harvest. After submitting a tender, we look back at how we got there. What did we do differently? What worked better? Where did we struggle, repeat ourselves or spend time correcting the output? Customer feedback and win/loss lessons can come later; we can start learning about the work straight away.
The useful question is what we should carry forward. Was an improvement specific to that opportunity, or would it make the framework better for the next one? It might be a clearer instruction, a better template, a reusable script or a change to how an agent approaches the job. Customer-specific information stays with the engagement; a general lesson can become a proposed improvement to the method.
That gives the review somewhere to go. We can assess the change, test it and look for evidence in later work that it helped. Did it reduce repeated explanation? Did the first draft need fewer corrections? Did we get a better result with the effort and capacity available? A lesson should earn its place in the shared method rather than become a new rule because one opportunity was unusual.
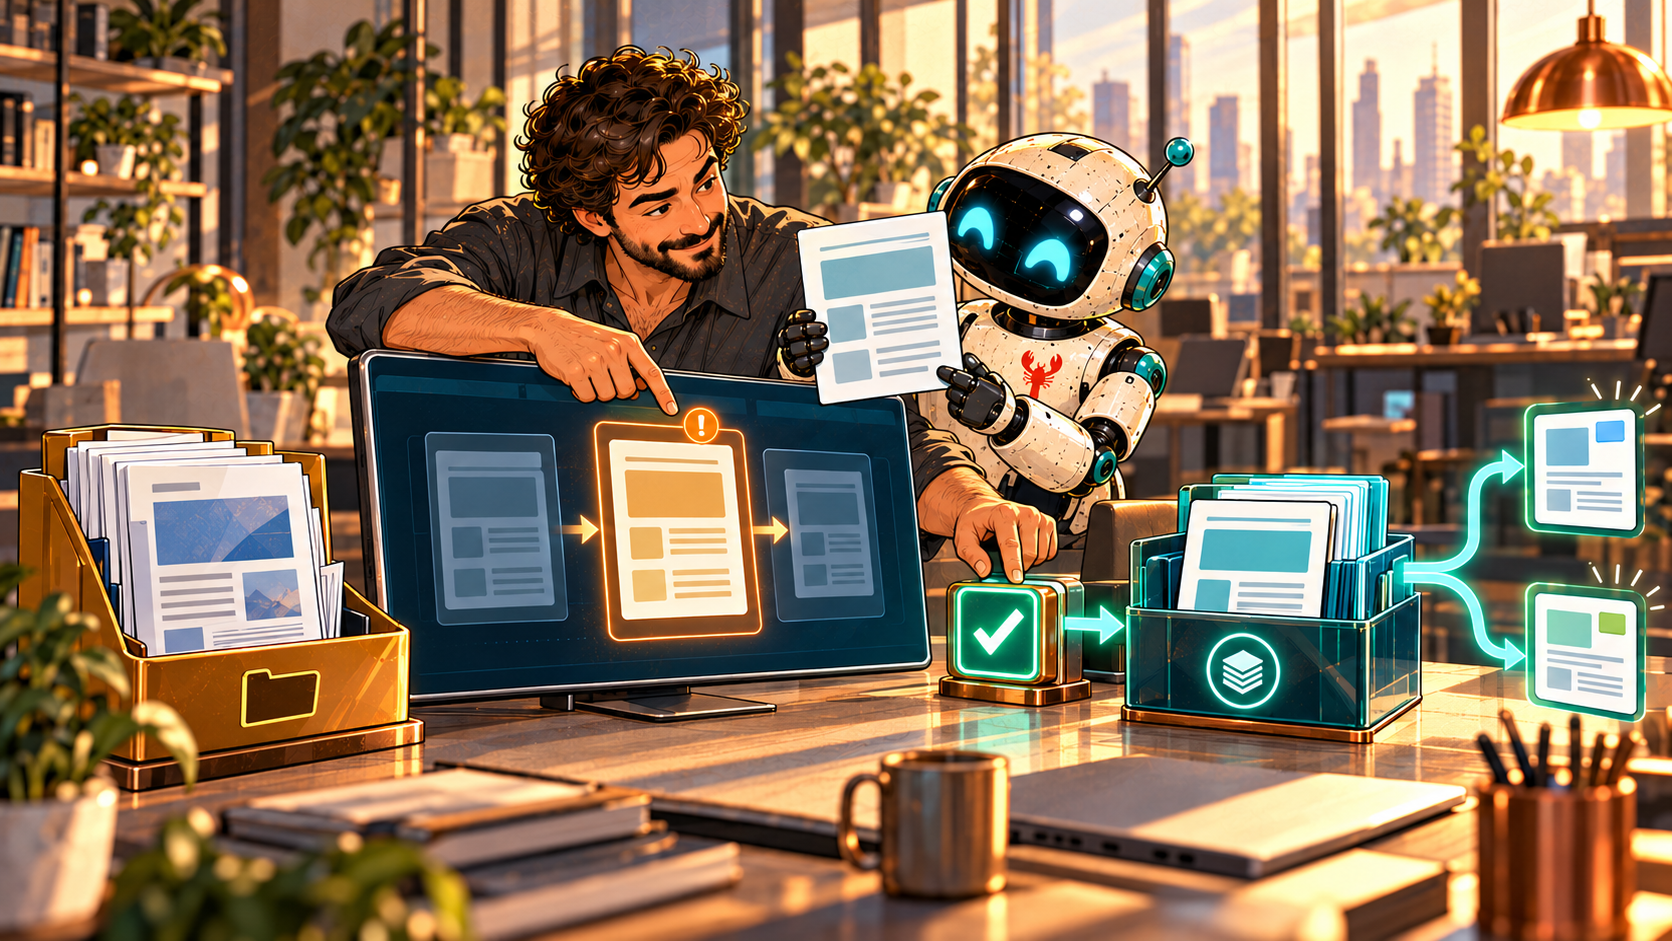
Read the image description
A completed engagement informs a retrospective. General improvements are proposed, reviewed and tested before reuse. Customer-specific records remain with the original engagement. This illustration depicts the intended learning process, not an automatically self-modifying agent or a measured savings result.
FinOps calls the connection between spending and what it produces unit economics. At my scale, I can start with a few comparable jobs and include the model usage, my own time and the effort to reach a usable result. A count of prompts or generated files would leave out most of what I care about.
Spending some additional model and human effort on the review may be worthwhile if it helps us avoid repeating the same problems. I don't yet have a measured subscription saving from these examples. The harvest gives us a way to propose improvements and then check whether they hold up in later work.
Even with the same subscription bill, completing more useful work with less correction could be a good return. Sometimes keeping capacity available for an unexpected problem is valuable too. I should be able to recognise that without feeling obliged to fill every bit of the meter before reset.
The same question gets bigger in the enterprise
An organisation has more people, more services and more complicated costs, but it still needs to connect the spend with the work. A low price per token tells us something about one resource. It does not tell us what it took to resolve the case, produce the response or reach a decision someone could act on.
This also becomes a question of how we help people use AI well. An employee might see one request and one answer. Behind that interaction could be several agents, repeated model calls and a growing amount of context. The consumption is not necessarily obvious to the person asking for the work.
We cannot expect everyone to become an expert in token accounting. We can give people practical guidance, useful visibility and sensible defaults. Which approved tools and models suit which jobs? When is another review worthwhile? When should an agent stop retrying and ask for help? Who can approve additional spend when the work justifies it?
That needs support from the platform too: budgets appropriate to the task, warnings about unusual consumption and limits on retries or agent activity that can pause an unproductive loop. A policy document alone will not stop an agent doing expensive laps. People need room to work within clear boundaries, with a way to escalate when the job genuinely needs more.
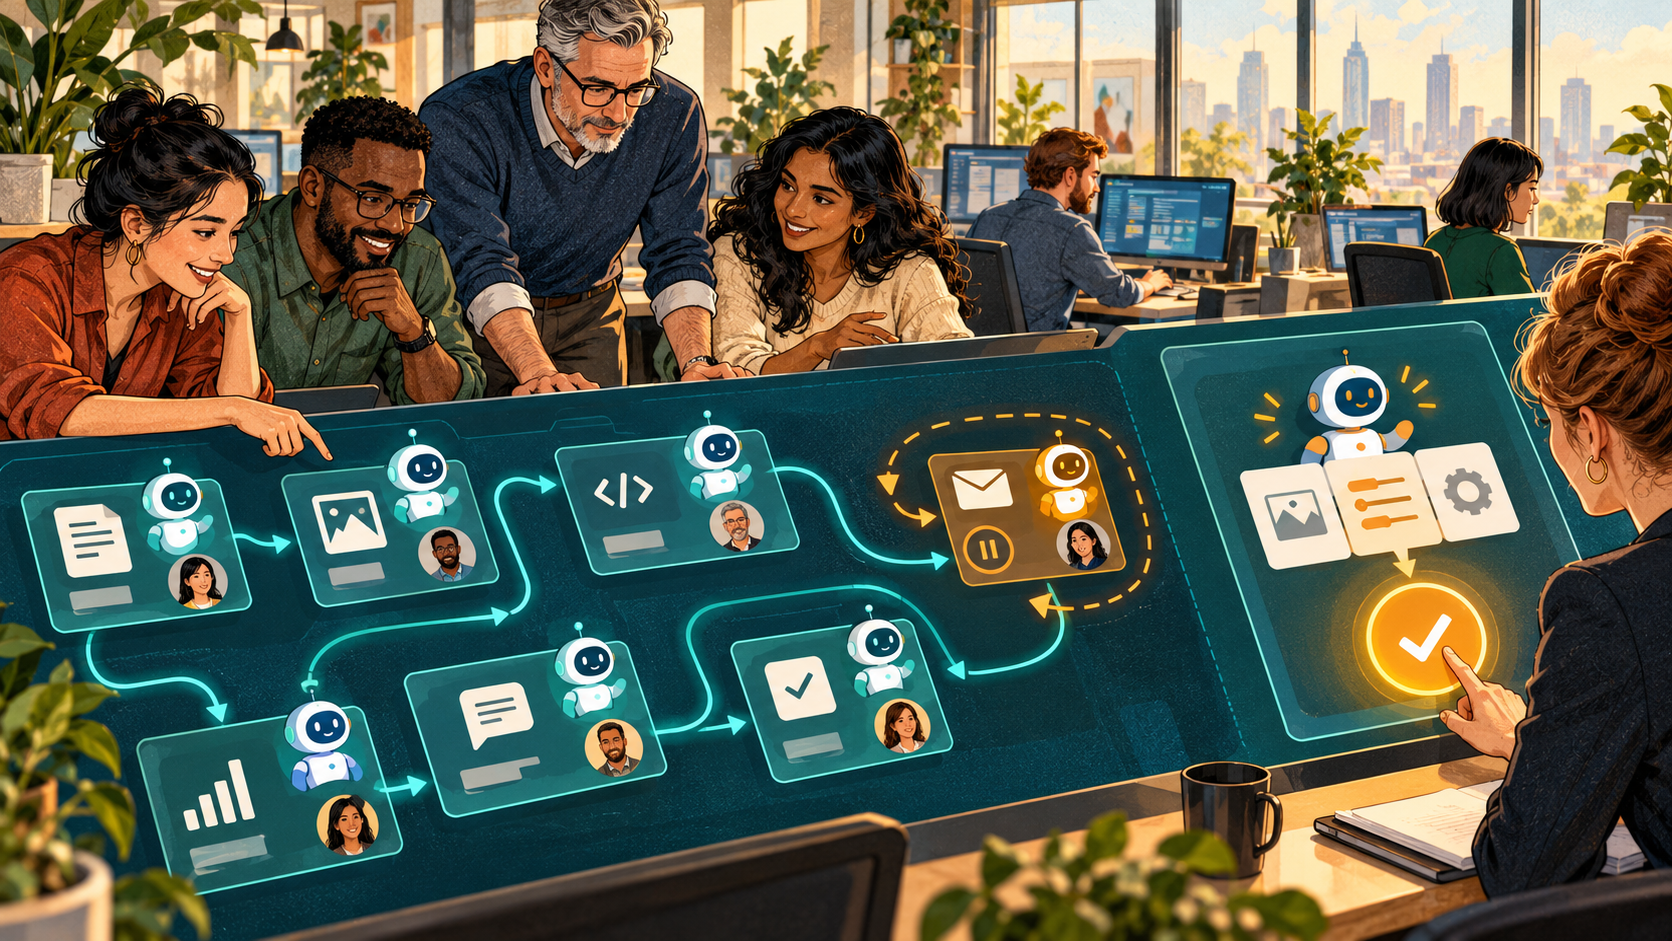
Read the image description
Most work proceeds within its boundaries. An unproductive loop is paused for attention, while a demanding job can request approval for additional capacity. These are proposed governance concepts, not a screenshot of deployed controls or a comparison of employee productivity.
I would want to understand the total cost of reaching a result the business could use. Model consumption, tools, infrastructure, human review, corrections and maintenance all contribute. Someone who spends more on a well-supported decision may deliver better value than someone whose inexpensive output creates another afternoon of work.
The harvest process can help the wider team too. Reviewed improvements can become a better starting point for the next employee or agent team, rather than remain something one person learned the hard way. We can improve the way work is done while checking that the quality and required controls still hold.
That is the connection I want to make between the enterprise conversation and the meter I keep checking myself. I want better use of the capability I already have, a clear reason for any extra spend and results that justify the effort around them.
I still don't particularly like leaving allowance unused. But I paid for access to useful help. That doesn't mean I need to find a job for every bit of allowance before it resets.
When the next week comes around, I would rather be able to point to something worthwhile that moved forward—and understand what helped me get it there.
Optional supporting reading
The FinOps Foundation provides further background on the ideas used here: